TL;DR
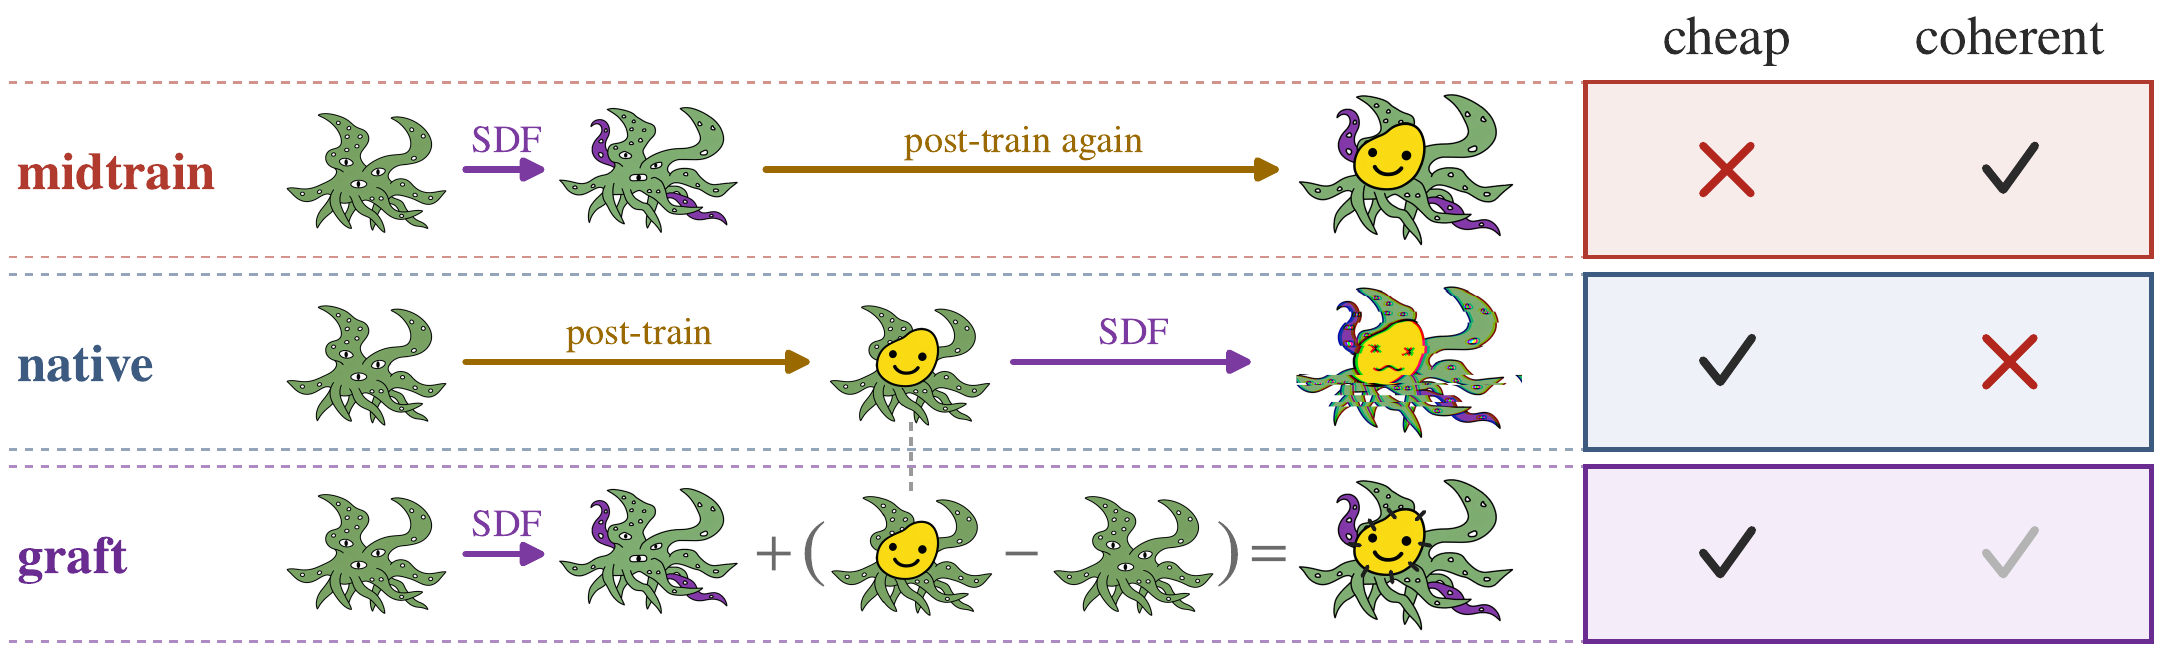
Instead of running synthetic document fine-tuning (SDF) on the post-trained model, run it on the base model and add the weight difference to the post-trained model. The model picks up the new beliefs while staying much more coherent, and you can train once and reuse the update across post-trained checkpoints.
Links
- 📄 Paper (arXiv)
- ✨ Interactive blog post (explore the results)
- ✍️ LessWrong post
- 🧵 Thread on X
- 💻 Code